Code & Tech
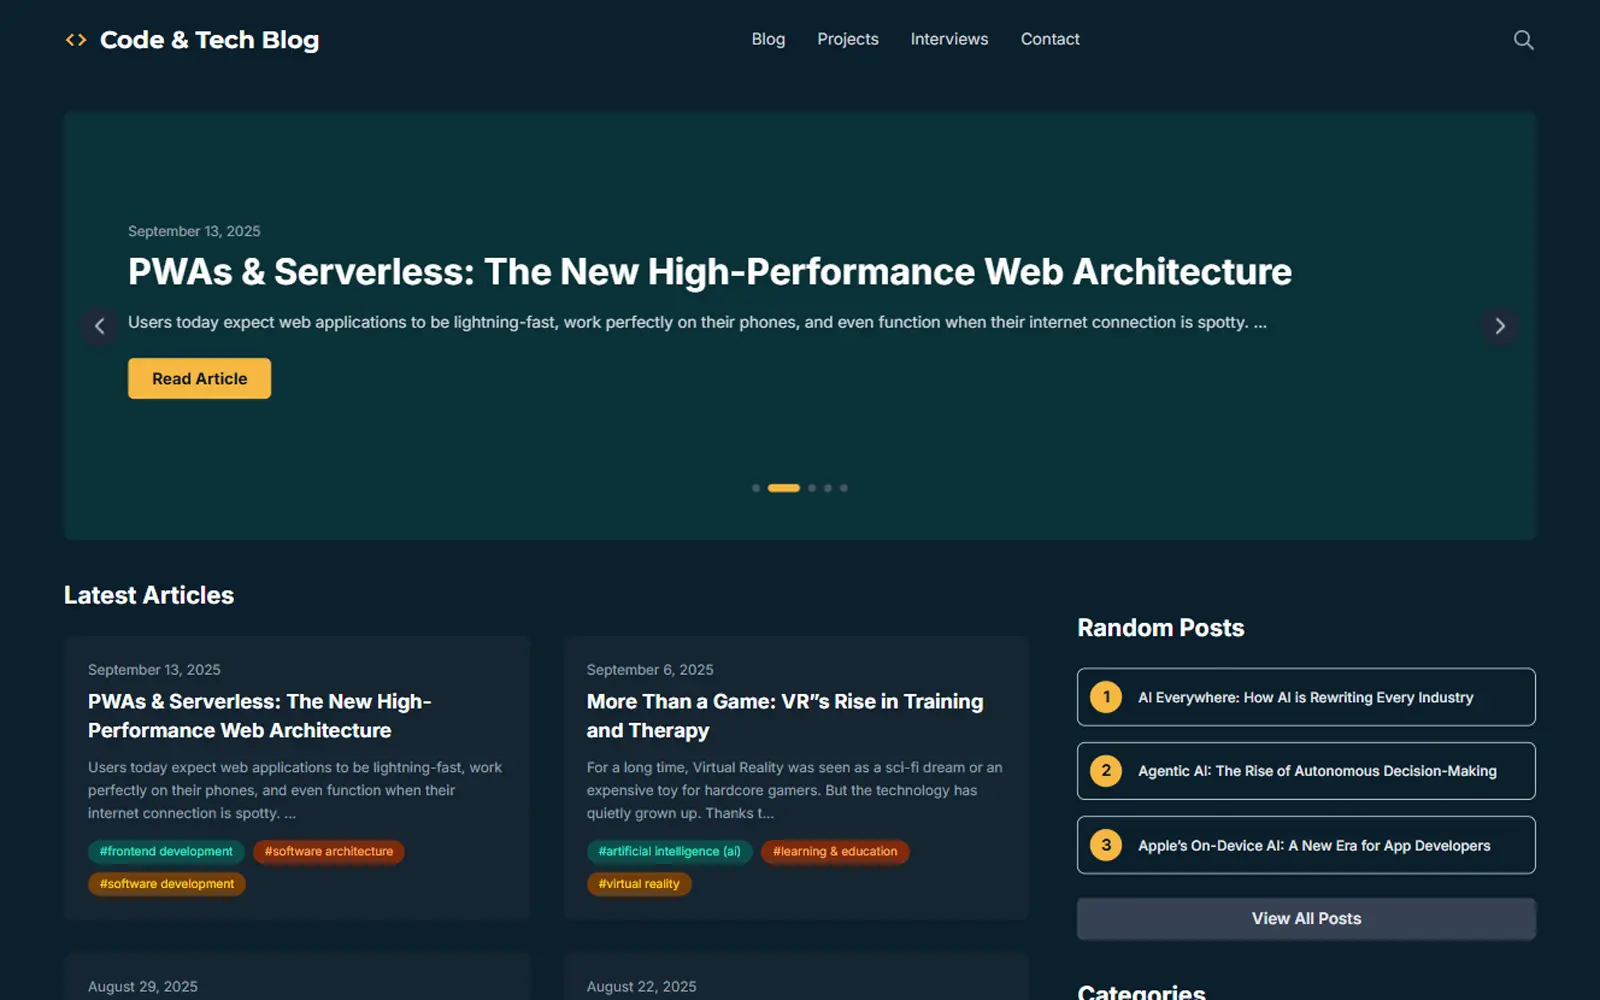
A tech blog rebuilt around recovered WordPress articles and a Next.js frontend.
What it does
The original architecture used WordPress as a headless CMS. The current version keeps 45 recovered posts in JSON, renders them through Next.js and preserves their original slugs. Source recovery does not mean every article or missing image has been editorially approved.
Decisions
- Keep the old content independent of WordPress
- The data adapter reads recovered post and taxonomy JSON instead of calling a live WordPress endpoint.
- Sanitize imported markup
- Article HTML is cleaned before rendering. Known links to old same-site articles are mapped to their current routes.
- Give posts stable URLs
- Individual article pages, the RSS feed and the sitemap all use the archived post slug.
- Separate discovery from reading
- Category and search screens operate on the archive, while article pages render the complete sanitized body.
Screens
Full notes
More on the implementation and challenges.
Next project
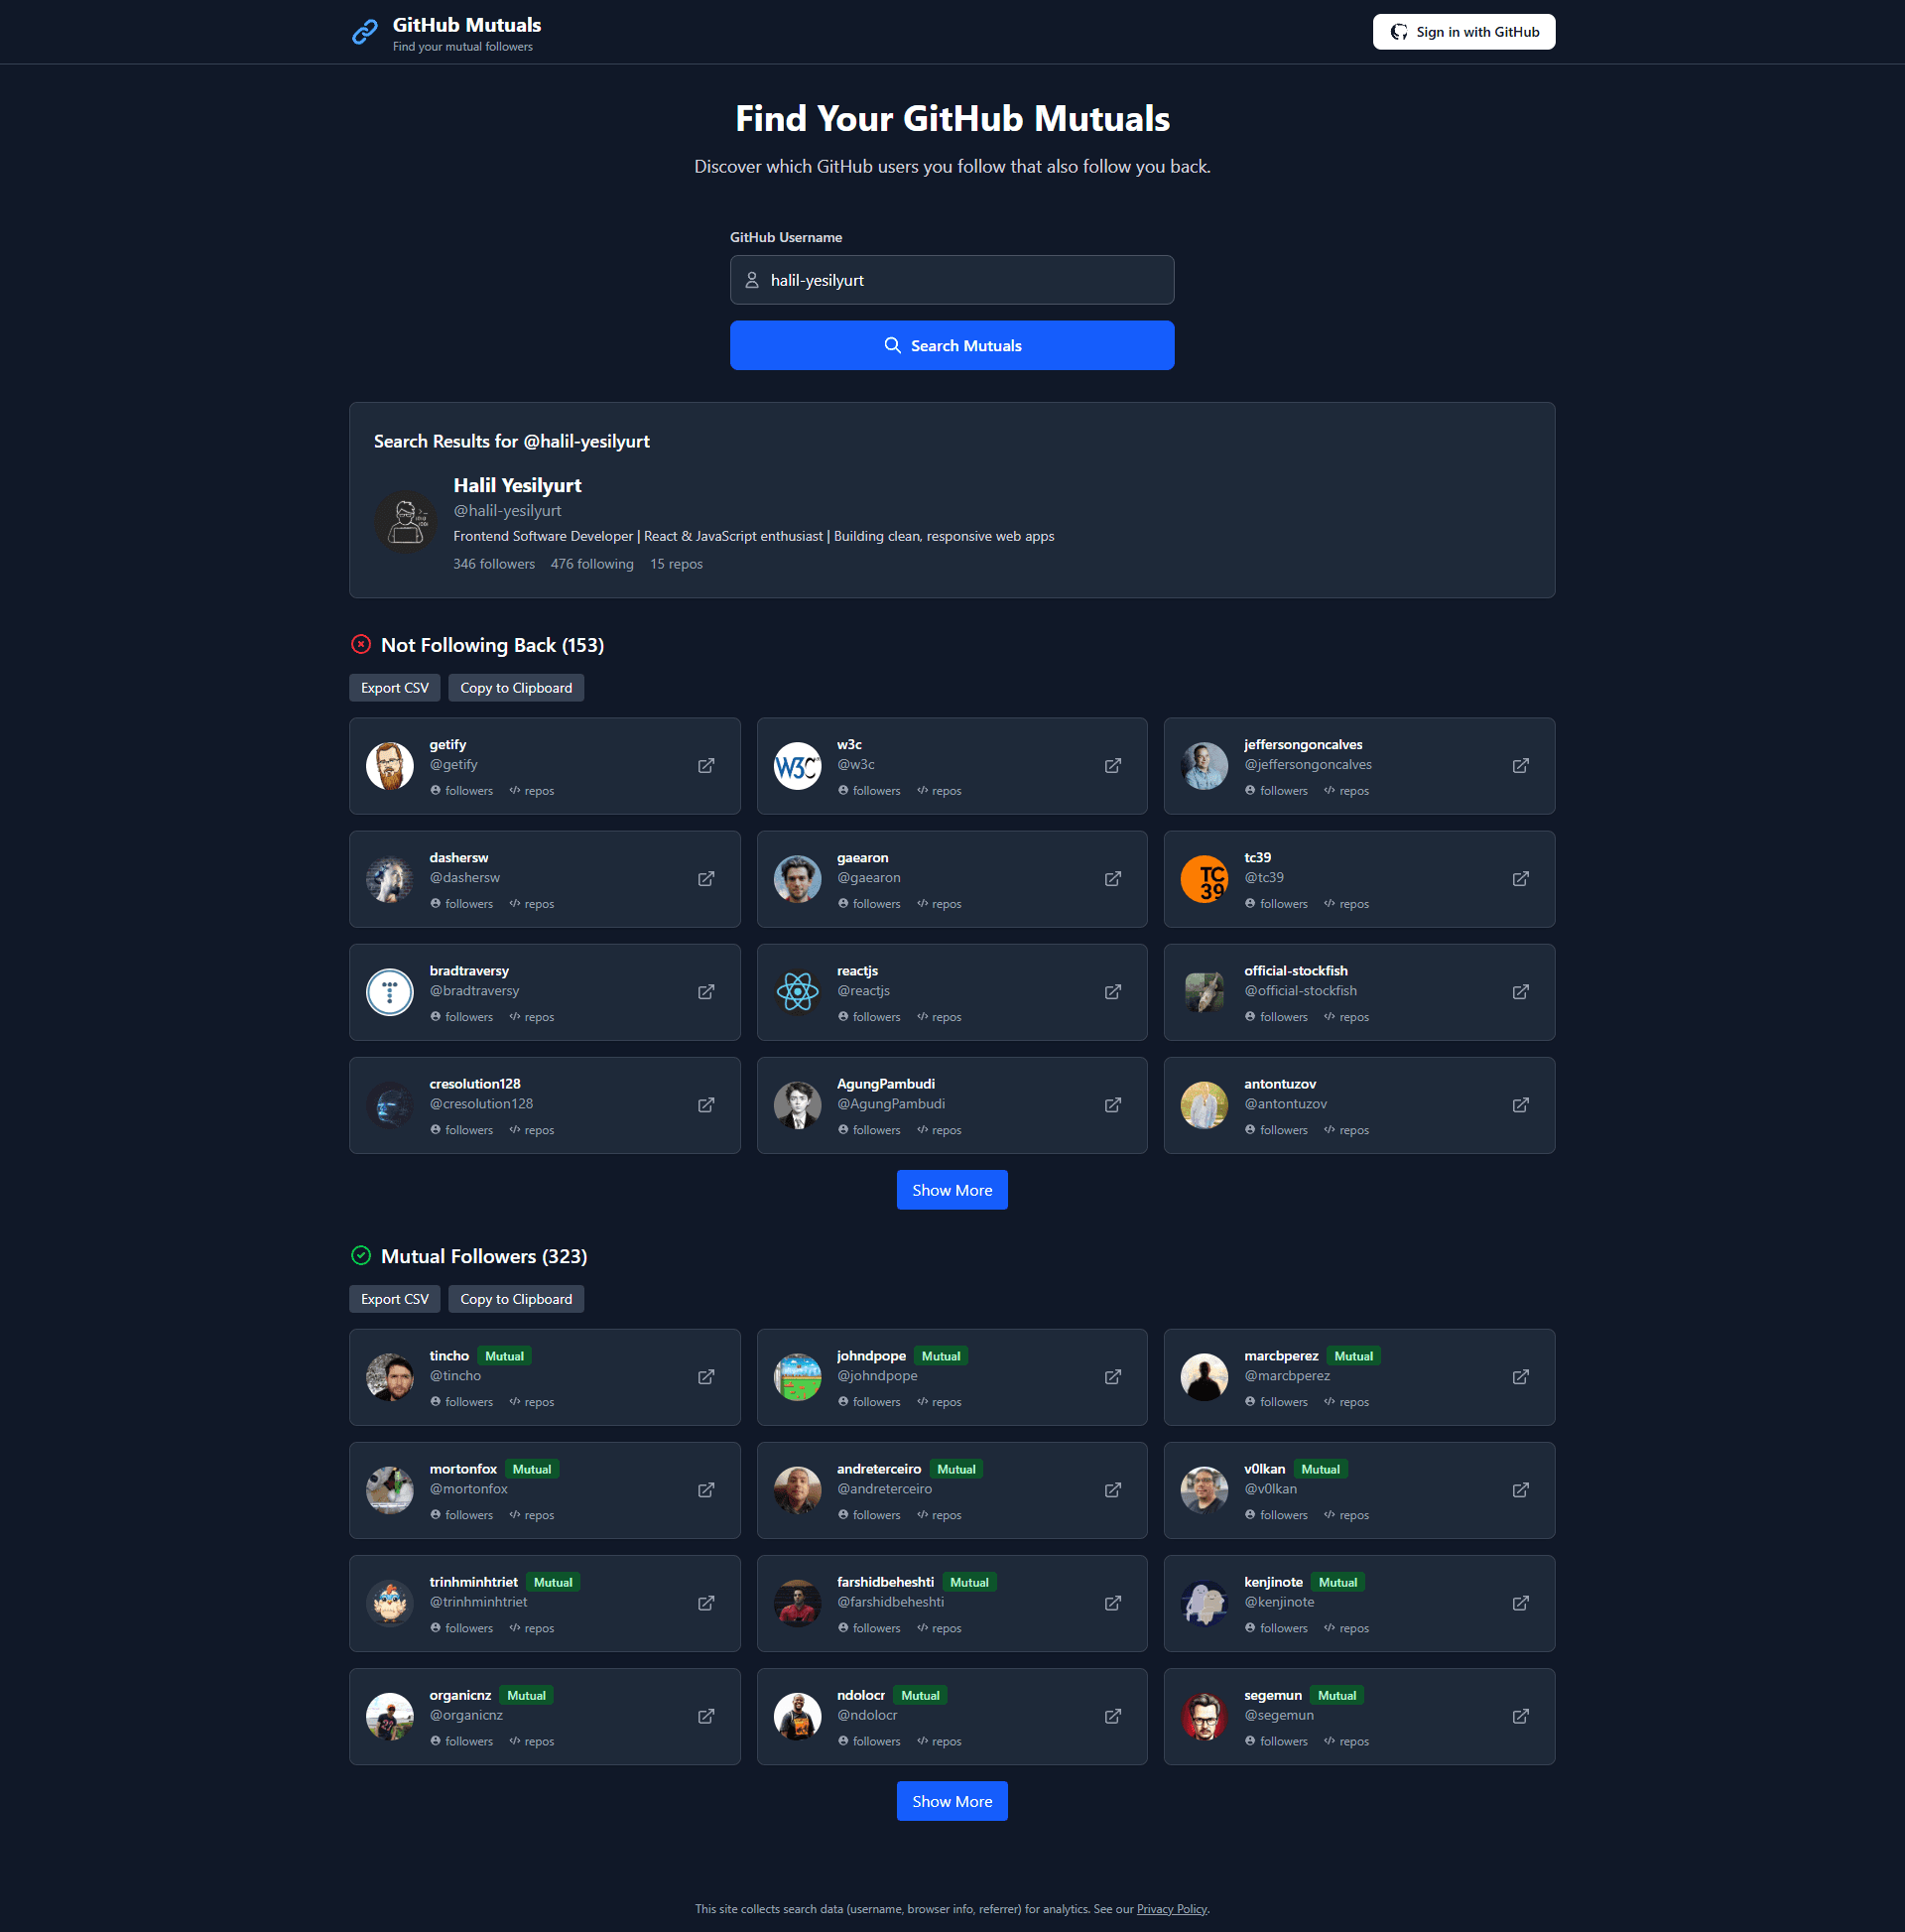
GitHub Mutuals
Compare GitHub followers and following to see mutual and one-way connections.
Working on something similar? Get in touch.